Someone is about to buy, opens a chat with a language model and asks what to choose. The answer arrives ready-made: a few names, a short justification, sometimes a link. No click on a search result, no visit to the brand's website, no trace in any dashboard. Analytics shows nothing, yet the decision has just been made. So where was the customer's attention? In the model's answer. And it was the model that decided who got it.
The language model as influencer: five rungs a brand climbs to reach customer attention
Today a language model works like an influencer, only on different terms. It has no reach you can buy and it signs no contracts. It decides whom to show at the moment the question is asked, and its recommendation reaches the customer at exactly the moment of choice.
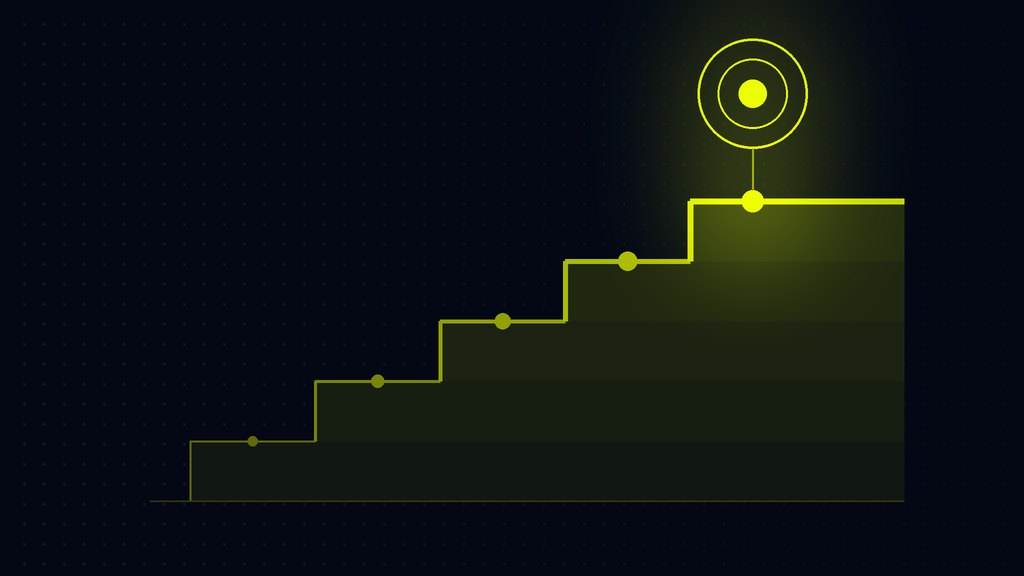
In my piece on the death of rankings I argued that position in search results had stopped being the measure that matters, replaced by the probability that a model recommends the brand. Michał Grzebyk described on this blog what brand visibility in model answers means. Both pieces are rungs on the same ladder. Here I climb one more, because neither presence alone nor recommendation alone tells us whether a brand has a chance of the customer's attention.
I break that chance down into five rungs: presence, competition, position, direction and hand-off. Together they form the attention-chance ladder. Each rung is a simple question a marketer can ask about their own brand, and together they describe what the model puts in front of the customer. Whether the customer actually reads it is a separate matter, which I return to at the end.
Where do the numbers in this article come from?
Every figure here comes from a single study of our own. It concerns one specific brand, which I call Brand A, and a set of scenarios built for its situation: 1,400 questions in 11 languages, asked on behalf of personas from 12 markets, put to six models (ChatGPT, Gemini, Claude, Perplexity, Grok, DeepSeek). That produced 8,400 assessed answers, collected between August and October 2026.
These percentages therefore describe Brand A, its questions and the model versions of that period. They are not a market norm, nor a level against which to hold another brand. A different category, different questions and different personas will produce different numbers. I show them because they illustrate mechanisms we also see when measuring other brands: the direction of the effect is similar, but the level always has to be measured separately.
Why does a single model answer tell you nothing yet?
Take one question from the study, asked in the language of one of the markets, without any brand name. Six models gave six different answers. In two, Brand A did not appear at all. In one it came fourth, introduced as "a surprise". In another it got a section of its own, in another a single mention in a sentence about living costs, and in the last it came third on the list.
Four models out of six brought the brand into their answer. Is that a good result? One question cannot tell you. Across the whole group of similar questions, the model brought Brand A in 45.1% of 324 answers, so in fewer than one answer in two. A single answer is like one throw of a loaded die: the die has its tendencies, but the outcome of one throw is chance. Only a fixed set of questions, asked many times, with the model version and date beside every figure, reveals those tendencies.
This study shows one more thing. The differences between types of question were larger than the differences between models. What the customer asks weighs more than which model they use. That is why preparing a study starts with an accurate description of the brand and of the situations in which customers look for it. We cover this in our series on preparing a study of model answers.
Five questions worth asking about your own brand
Does the model bring the brand into the answer by itself?
The first rung is presence. When the brand name is in the question, the model talks about it almost always: in the Brand A study, in 99.9% of answers. That is an echo, though, not a measurement. The real test begins where the customer does not name the brand, because only there does the model itself choose whom to give a chance.
In 1,452 answers to questions without Brand A's name, the model brought it in 72.4% of cases. That average hides large differences. In questions from private individuals (which the following figures refer to unless I say otherwise) narrowed to the segment where the brand competes, it appeared in 91.7% of 552 answers. In general questions about the whole category, in 45.1% of 324. In questions that did not point to the category at all, in 20.0% of 90. Presence, then, is not a property of the brand. It is a property of a pair: the brand and the question.
Who does the brand share the answer with?
The second rung is competition. A model rarely points to a single brand. In 1,044 answers to questions without Brand A's name, it listed on average almost six other options, and Brand A was the only suggestion in just 0.4% of cases. In general questions the list was opened by a leader, named in 58.0% of answers. Brand A came second (45.1%), with four options close behind, each named in 38–41% of answers.
The conclusion is simple: in a model's answer a brand competes not with one rival but with an entire list. The model that compiles that list decides whom the customer will see next to your brand.
How high does the brand stand in the answer?
The third rung is position: at the top of the answer or in the eighth paragraph. In the single-question example, Brand A stood third once and fourth once. It is tempting to turn that into a ranking. Yet the Brand A study shows that when the brand name is not in the question, its position changes from answer to answer, even when the same question is repeated on the same day.
A single position, then, is not a result. The result is how often the brand reaches the opening of the answer across a fixed set of questions. When the brand name is in the question, the model almost always opens its answer with it, but that, again, is only an echo.
Does the model recommend, merely mention or advise against?
The fourth rung is direction. When the model brought Brand A into the answer by itself, it clearly recommended it in 55.9% of cases. It almost never advised against it (1.7%), but in four answers out of ten it merely mentioned it, with no recommendation at all. Michał Grzebyk explains the difference between a mention and a recommendation in a separate piece.
The most interesting part is that question type works the other way round here than it does for presence. In narrowed questions Brand A appears almost always, yet it is recommended in only 47.0% of answers. In general questions it appears less often, but when it does appear it is recommended in 62.3%. Presence by obligation is not the same as presence by choice. The model chooses a brand when it has an argument for it, and a mention counter cannot tell the two situations apart.
Where does the model send the customer?
The fifth rung is hand-off. This is where the model's channel ends and your website begins. Addresses that models gave from memory led to pages connected with Brand A in 49.5% of cases. Sources found through live search led there in 22.4%. These are two different modes of working and two separate figures, which I do not combine into one.
Reading the answers shows why. The model cites a source that addresses the asker's situation, in their language and context. It does not cite a text about who the brand is. For any content publisher that is an important signal: traffic from models goes to the page that answers the customer's question.
The chance of attention is a snapshot
The five rungs describe answers from a specific day and a specific model version. In the Brand A study, newer model versions shifted the share of clear recommendations by more than ten points in seven weeks, in both directions and without any campaign. One model, in its new version, stopped naming the brand in an answer where it had previously been on the list. Another, in its new version, put it in the first sentence.
Drift of this kind changes the meaning of any one-off audit. A figure without a model version and date has no address, and a measurement from a quarter ago only tells you how things were. The chance of attention needs to be checked regularly, on the same set of questions.
Why is a well-known brand not yet a seen brand?
Asked directly for the best-known names associated with Brand A, the models gave the same canon in every one of 144 answers. In practical questions that same canon appeared in between 12.0% and 0.8% of answers. Knowledge enters an answer only through a door that the customer's question opens: a place, a problem, a specific situation. In business questions, the source that met a practical need ("how do I check a business partner?") appeared in 143 of 4,200 answers, while the largest company in the same landscape appeared in 21.
So the model does not recommend what it knows best. It recommends what fits the question. That is why a brand's content has to be built around customers' situations, not around its own description.
A chance of attention is not yet attention
The five rungs tell you what the model puts in front of the customer. What the customer actually reads and processes is shown only by methods involving people, such as a survey or eye tracking on samples of answers. That is where attention, in the strict sense, begins. In advertising, part of attention is estimated from data signals such as exposure time or scrolling. In a model's answer those signals belong solely to the platform that displays it, so from the outside only the content of the answer can be read. The route to attention in the AI channel therefore has four steps.
First, questions without the brand name: a fixed set of customer questions, many runs, and the model version and date beside every result. Second, the five rungs read from the content of the answers, which is the chance of attention. Third, research involving people, which confirms attention. Fourth, the business outcome: traffic from answers, enquiries, sales and brand lift, linked to steps two and three.
Alongside this route sits a separate tool: an audit of representation quality. The 5P model, described on the Brand Semantics blog, checks whether an answer is true and whether the result is stable. The attention-chance ladder describes the brand's route to the customer, while 5P describes the quality of what the model says along the way.
What follows for a marketer, whatever the tool?
I have gathered it into five principles that hold whatever you measure with.
- Measure where the customer does not name the brand. Questions that include the brand name are an echo, not a measurement. The chance of attention is decided by questions about the category, the problem and the situation.
- Do not count mentions. Count mentions with a reason: an argument, a place, a comparison. A mention without a reason takes a spot on the list but gives the customer no reason to choose.
- Give the model a door. A fact, a number or a comparison prepared for the customer's question gets into the answer. A text about who you are usually does not.
- Study the audience's question in their language and context. Only then can the answer send people to you, rather than to a source that fits the customer's situation better.
- Every figure with a model version and date. Measure regularly, and count paid advertising in the chat separately from the model's mention.
Attention is becoming a currency. In a model's answer the chances of winning it are handed out by the model, and they go to the brand that gives it a reason.
If you want to check these five rungs for your own brand, Semantio asks models questions without the brand name and shows whether the model brings the brand in, who it is set alongside, how strongly it is recommended and where the model sends people next. You can start with a 7-day trial.
Read also: ChatGPT will show how often a brand appeared in answers. It will not show why